新一代ChatGLM2-6B 模型开箱|中文LLM要崛起了?
ChatGLM2-6B 上手记录:模型体验、量化加载、本地部署,以及推理架构与对话方法的代码分析。
原文刊载于微信公众号「布尔艺数」,发布日期:2023-07-07。查看原文。以下为当时发布的内容。
2天前当我还在抓头皮想办法提升微调baichuan-7B的时候💤,突然刷到ChatGLM2发布了 💀。当时的我还没有意识到问题的严重性,毕竟ChatGLM出道还没有半年,而且试用效果感觉一般,于是没有抱什么期待的,我在本地玩耍了一下ChatGLM2,发现事情好像并没有那么简单。真实体验下来,效果似乎真的如官方评测结果显示的那样,模型性能有了巨大提升。
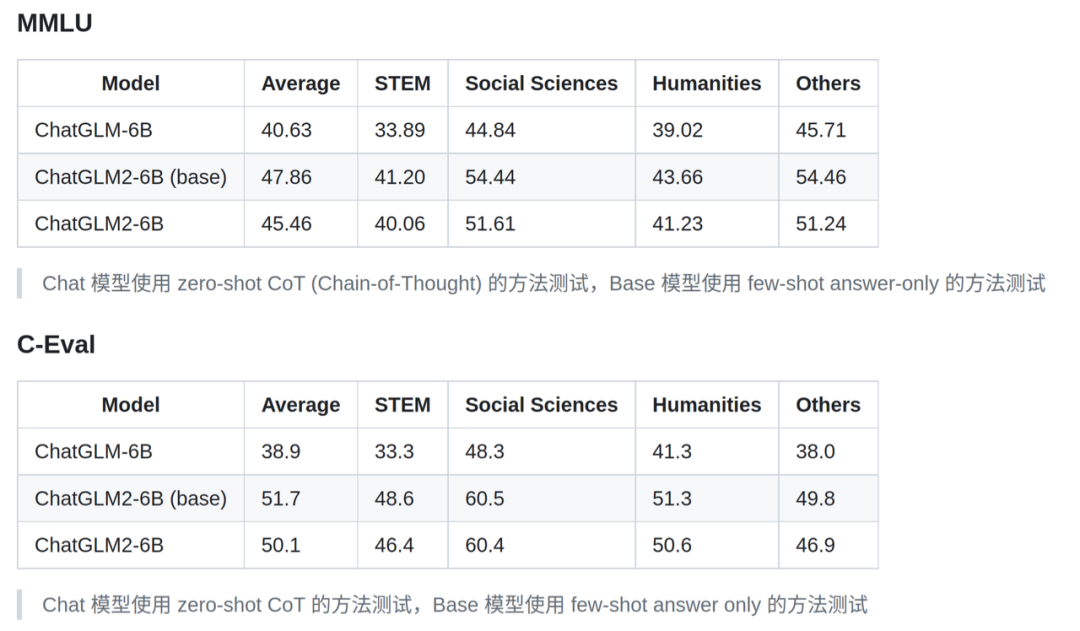
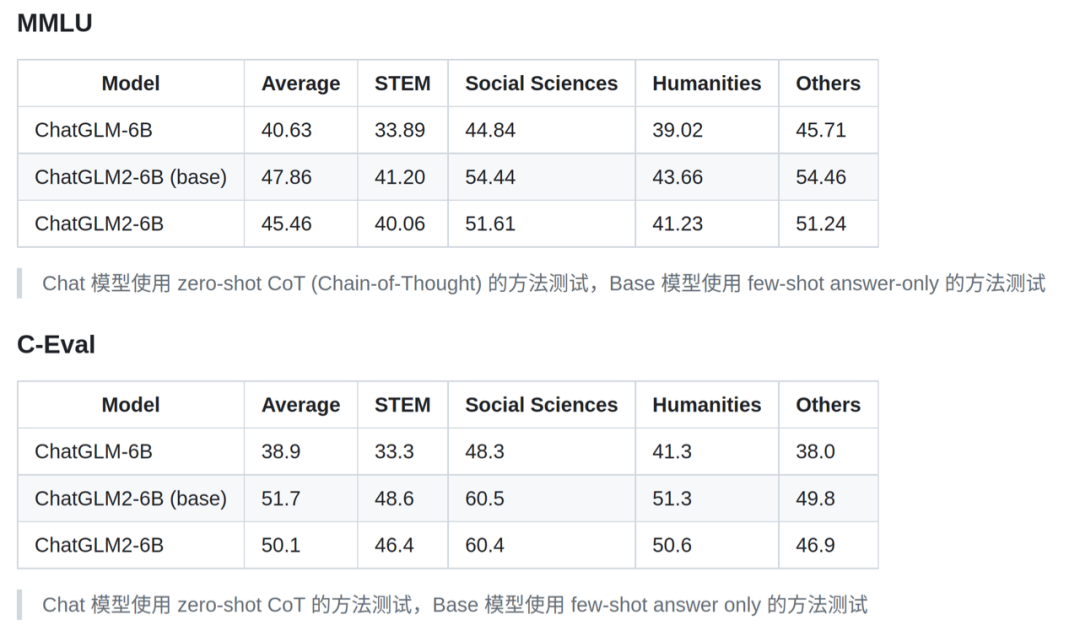
为了节省大家的时间,我就来做一个ChatGLM2简单的开箱:
- ChatGLM2体验
- 模型加载、量化、本地部署
- 从代码从面上来看,ChatGLM2做了哪些变化?(没论文,只能看代码了 🤯)
- 从模型的chat方法代码一窥chatLLM和普通的LLM有什么区别
1. ChatGLM2体验
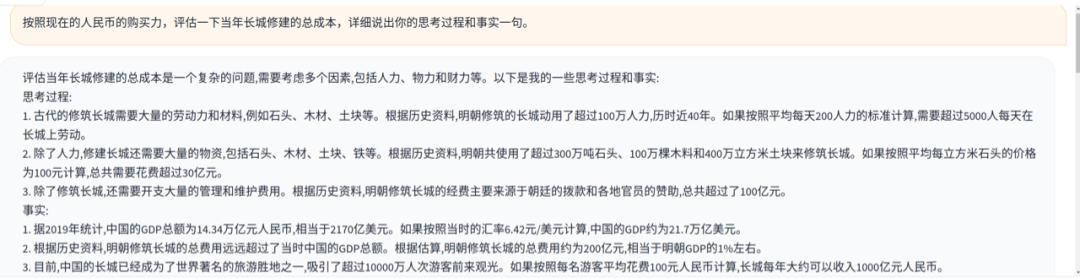
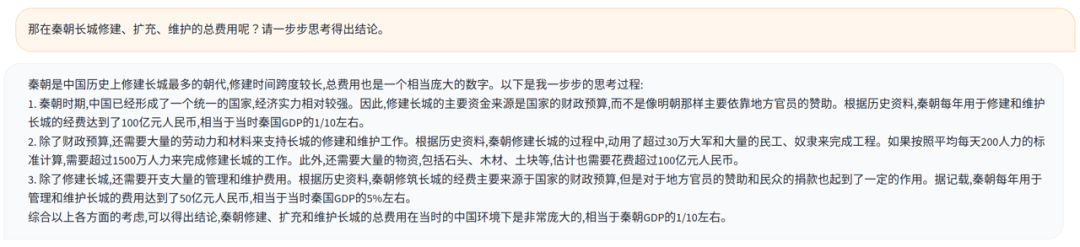
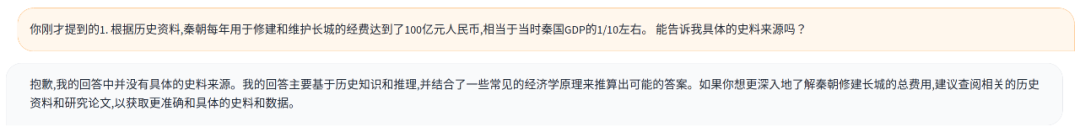
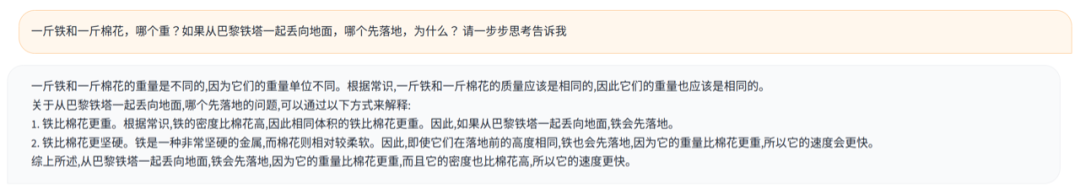
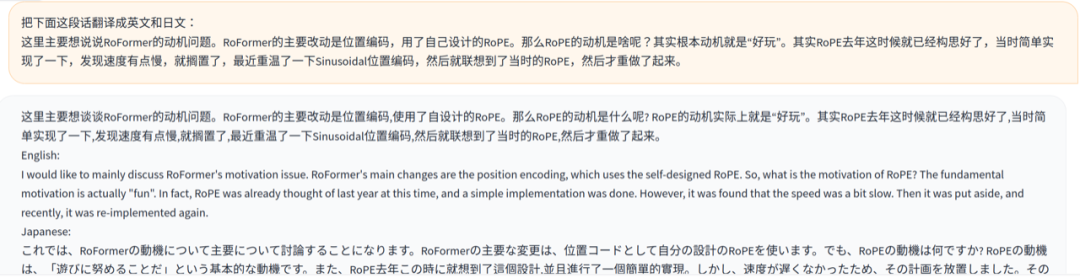
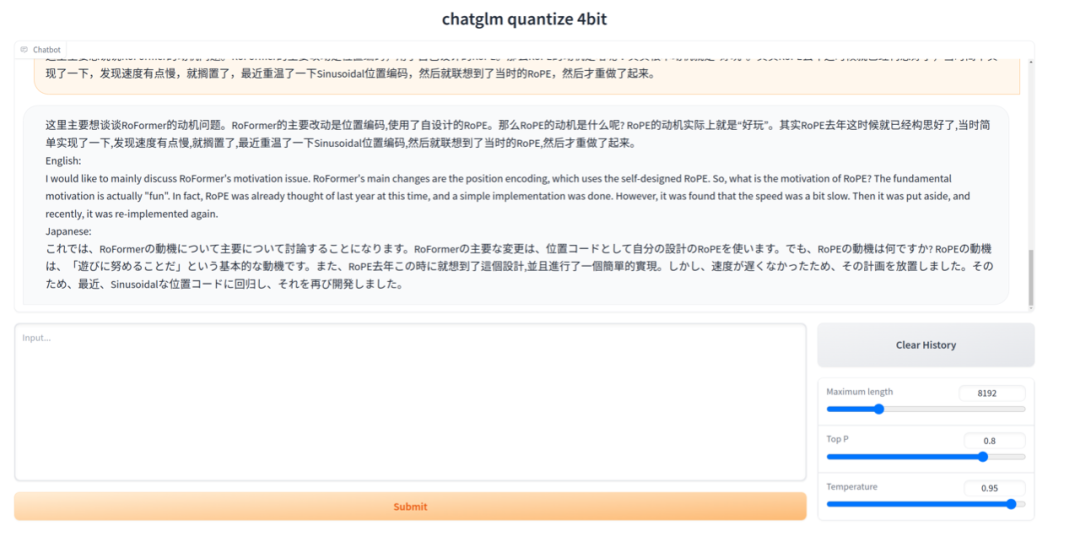
这里只能贴一部分,体验感受:整体效果较一代有了明显提升,简单任务基本能胜任,复杂推理能力较claude, chatGPT依然还有较大差距,猜测原因是受限于模型尺寸,6B还是太小了。
2. 模型量化加载及及部署
import os
import torch
from transformers import AutoModel, AutoTokenizer, AutoModelForCausalLM, BitsAndBytesConfig

def load_quantize_llm(model, model_ckpt, quantize='4bit', local_rank=None):
    if model.lower().startswith("baichuan"):
        AutoLoad = AutoModelForCausalLM
    elif model.lower().startswith("chatglm"):
        AutoLoad = AutoModel
    else:
        NotImplementedError

    device_map = {"": torch.cuda.current_device()}
    # if we are in a distributed setting, we need to set the device map and max memory per device
    local_rank = os.environ.get('LOCAL_RANK', local_rank)
    if local_rank is not None:
        device_map = {'': int(local_rank)}
        print(f"local rank {local_rank} map to {local_rank}")
    if quantize == '4bit':
        print("load model with 4bit quantization")
        model = AutoLoad.from_pretrained(
            model_ckpt,
            device_map=device_map,
            #                 load_in_4bit=True,
            torch_dtype=torch.float16,
            trust_remote_code=True,
            quantization_config=BitsAndBytesConfig(
                load_in_4bit=True,
                bnb_4bit_compute_dtype=torch.float16,
                bnb_4bit_use_double_quant=True,
                bnb_4bit_quant_type="nf4",
                llm_int8_threshold=6.0,
                llm_int8_has_fp16_weight=False,
            ),
        )
    elif quantize == '8bit':
        print("load model with 8bit quantization")
        model = AutoLoad.from_pretrained(
            model_ckpt,
            device_map=device_map,
            load_in_8bit=True,
            torch_dtype=torch.float16,
            trust_remote_code=True,
        )
    else:
        print("load model with fp16")
        model = AutoLoad.from_pretrained(
            model_ckpt,
            device_map=device_map,
            torch_dtype=torch.float16,
            trust_remote_code=True,
        )

    tokenizer = AutoTokenizer.from_pretrained(model_ckpt, trust_remote_code=True)
    if tokenizer.pad_token_id is None:
        print("pass unk_token_id to pad_token_id")
        tokenizer.pad_token_id = tokenizer.unk_token_id
    print(f'memory usage of model: {model.get_memory_footprint() / (1024 * 1024 * 1024):.2} GB')
    return model, tokenizer
大家可以参考上面贴的函数加载模型,支持int4, int8和标准精度加载模型,如果网络通常可以直接运行:
model, tokenizer = load_quantize_llm("ChatGLM", "THUDM/chatglm2-6b", "4bit")
如果网络不好的话,可以下载模型文件并传入模型文件的路径。
model, tokenizer = load_quantize_llm("ChatGLM", "model_ckpt_dir", "4bit")
要体验模型的话可以参考我的项目<https://github.com/EvilPsyCHo/train_custom_LLM>使用命令启动。
CUDA_VISIBLE_DEVICES=0 python.py webui.py --model {模型类型如 baichuan, chatGLM} --model_ckpt {模型权重文件路径} --quantize {4bit, 8bit}
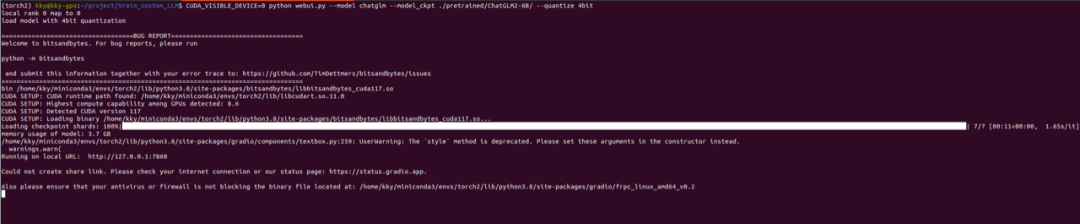
启动后进入命令行中URL在浏览器上进行体验:
3. ChatGLM2做了哪些变化?
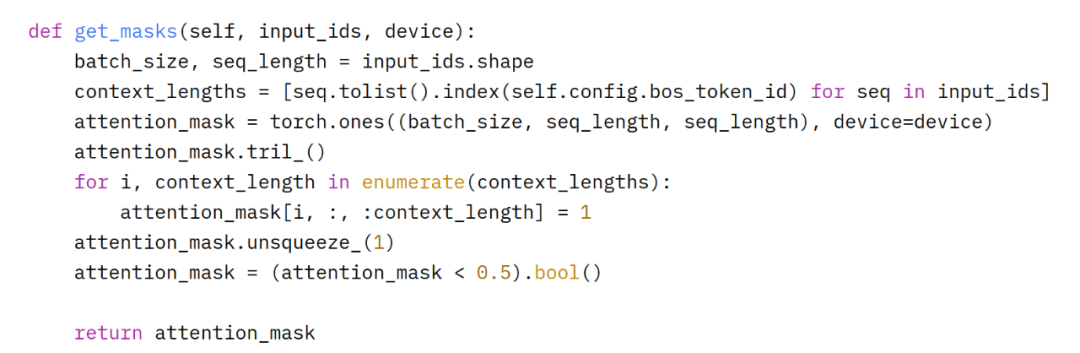
至少在推理端,变为了纯decoder-only架构了,在ChatGLM中的attention_mask构造函数可以看出,context_length部分是双向Attention , 后半部分才是causal Attention.
再看ChatGLM2的代码:
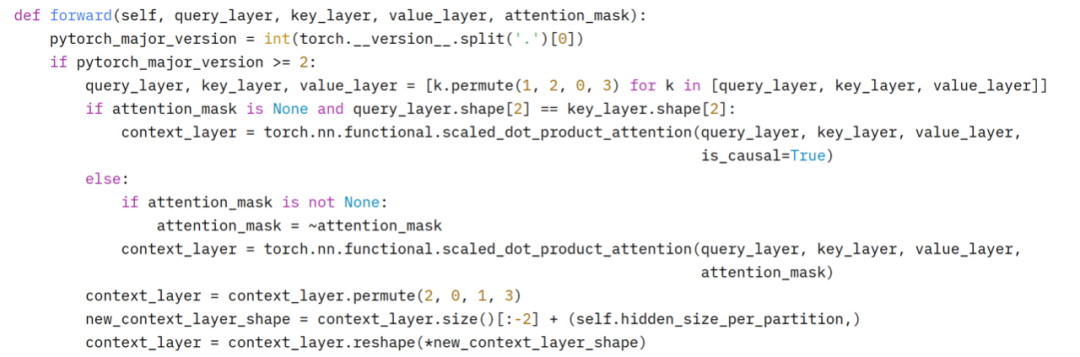
直接使用的pytorch 2.0实现的函数scaled_dot_product_attention,并设置is_causal=True,变为了纯decoder-only架构了.
4. 从模型的chat方法代码一窥chatLLM和普通的LLM有什么区别
对会话数据进行的pre-processing, 添加了轮次信息和区分用户和LLM的特殊token:
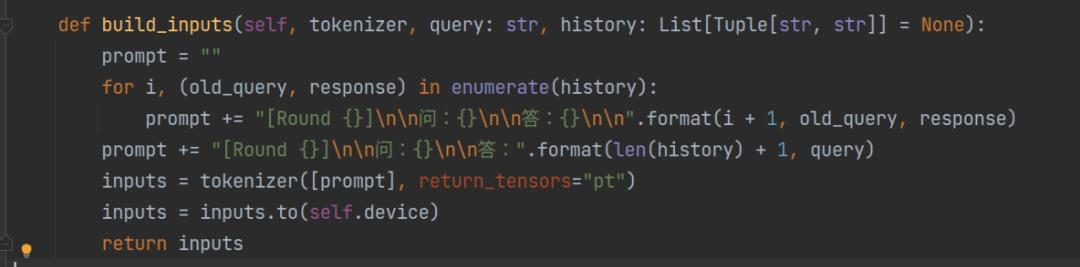
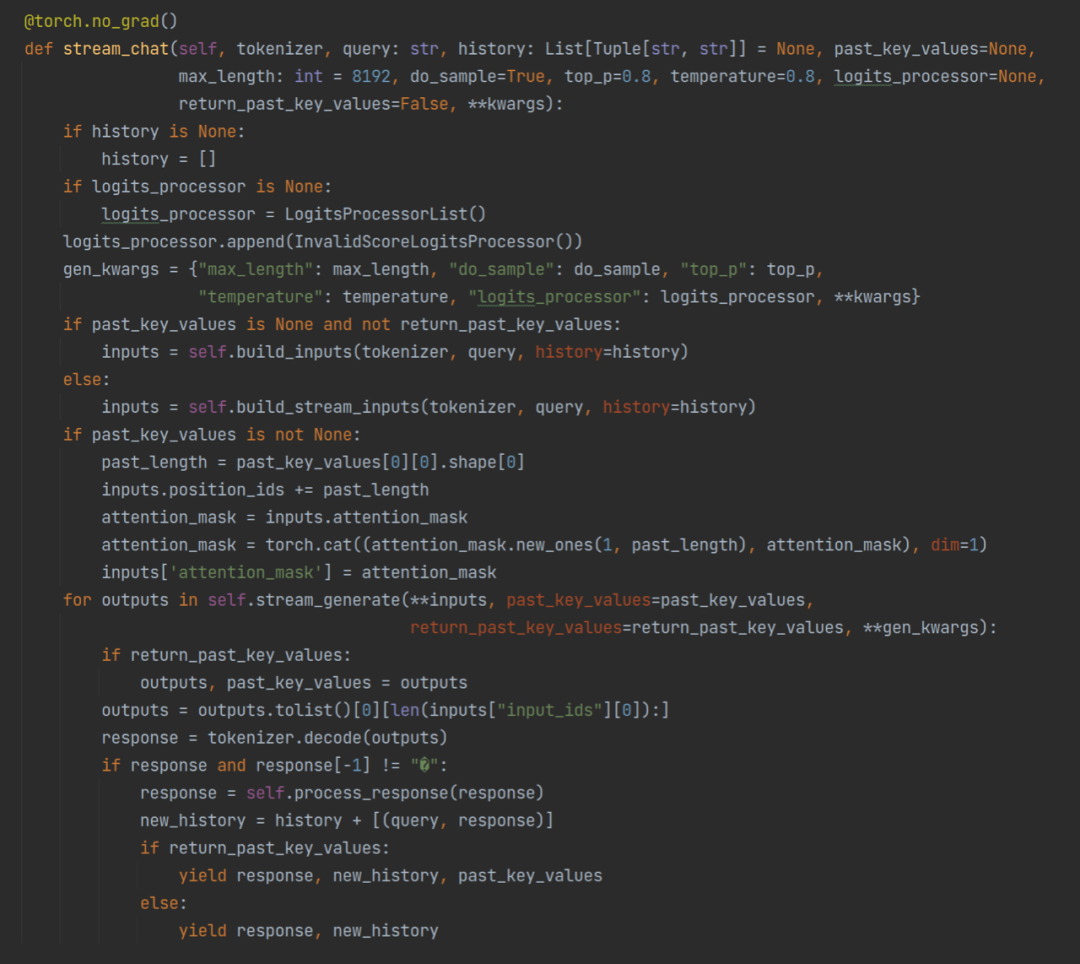
在对话中,模型显然需要考虑用户历史输入及模型历史回复,decoder-only架构下,因为只需要计算单边Attention,那么我们保存历史计算的attn_K, attn_V,再与新的input进行拼接,就可以直接生成后续回复了,计算量大大减少,因此有一个参数past_key_values 来传入历史计算的attn_K, attn_V.
Large scale Stable Diffiusion Image embedding retrieval system构建高质量大规模Stable Diffusion图片向量召回系统,支持基于prompt的快速出图。核心工作:
- 数据舍弃高prompt embedding similarity样本,过滤相似prompt,使得样本在语义空间的分布更加均衡;舍弃第clip prompt image similarity样本,提升数据质量;
- Image Encoder调研选取openai clip, open_clip, blip2等多模态模型,进行对比实验,权衡性能与速度选择open_clip-ConvNext-large@320和open_clip-ViT-L-336作为骨架网络;
- 模型输出投影层采用多模态方式进行预训练,利用open_clip文本-图像对齐特性,使用文本text-encoder对prompt embedding训练到目标语义空间的投影层,并讲该投影层权重作为image-encoder投影层权重的初始化;
- 采用结合Lora的分层学习率技巧,在最大化任务性能的前提下,尽可能open-clip预训练模型能泛化能力,具体来说将模型自底而上的layer划分为feeze-layer, lora-layer, finetune-layer,采用不同学习策略进行学习,使得泛化能力更强的底层layer保留原始权重后只训练lora旁路。
如果需要AIGC或者CV、NLP等方向相关辅导的,可以通过下图联系助教定制辅导方案